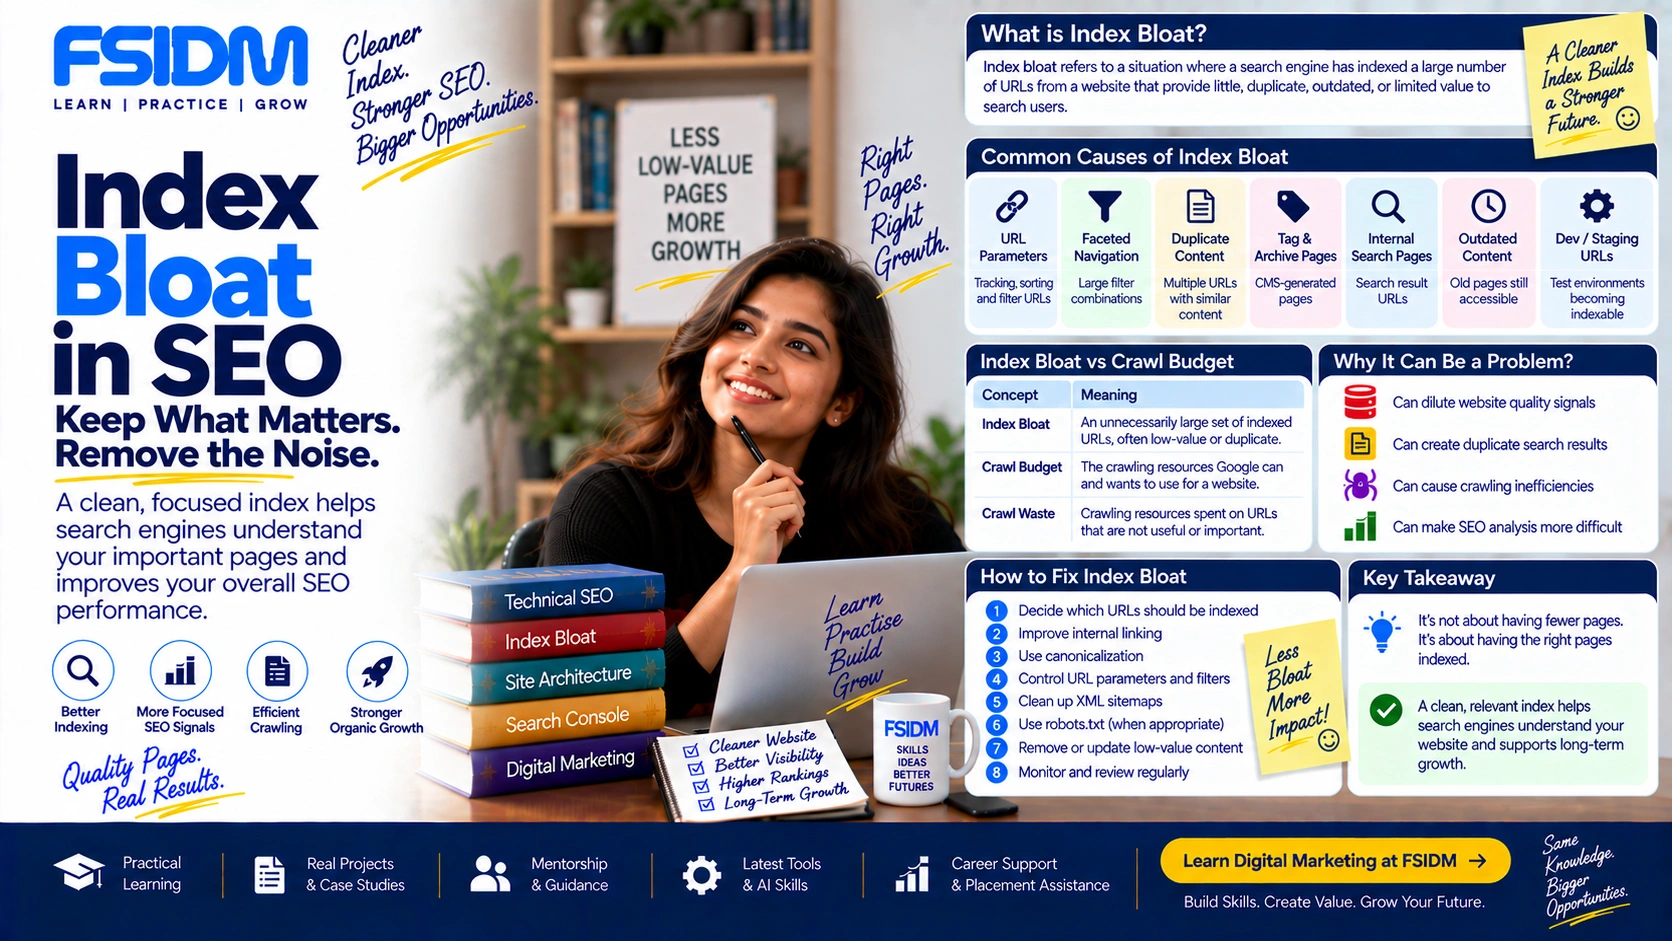
Index bloat refers to a situation where search engines have indexed a large number of URLs from a website that provide little, duplicate, outdated, or otherwise limited value to search users.
A website can have thousands of URLs without necessarily having an index-bloat problem. The real concern is whether a significant portion of the indexed URL set is unnecessary, low-value, duplicate, or not useful for search visibility.
What Is Index Bloat?
Search engines crawl webpages, evaluate them, and may choose some URLs for indexing. Over time, websites can unintentionally accumulate indexed URLs that do not meaningfully contribute to organic search.
For example, an ecommerce website might generate separate URLs for combinations of filters such as size, color, sorting, and price. If many of these variations become indexed without providing unique search value, the website may develop an unnecessarily large index footprint.
What Causes Index Bloat?
Index bloat can develop from several technical and content-related issues.
- URL parameters: Tracking, sorting, filtering, or session parameters can create multiple URL variations.
- Faceted navigation: Ecommerce filters can generate large numbers of combinations.
- Duplicate content: Multiple URLs may expose substantially similar content.
- Thin or low-value pages: Automatically generated pages may provide little unique information.
- Tag and archive pages: CMS-generated archives can create many pages with limited standalone value.
- Internal search pages: Search-result URLs can sometimes create large numbers of unnecessary pages.
- Outdated content: Old pages may remain accessible even when they no longer serve a useful purpose.
- Development or staging URLs: Test environments or unintended URLs can sometimes become discoverable and indexed.
Is Having Many Indexed Pages Bad for SEO?
Not necessarily. A large website can legitimately have hundreds of thousands or millions of valuable URLs. The number of indexed pages alone does not prove index bloat.
The important question is whether the indexed URLs are useful, distinct, accessible, and appropriate for search. A large index containing valuable product, category, article, location, or other relevant pages can be perfectly reasonable.
Index Bloat vs Crawl Budget
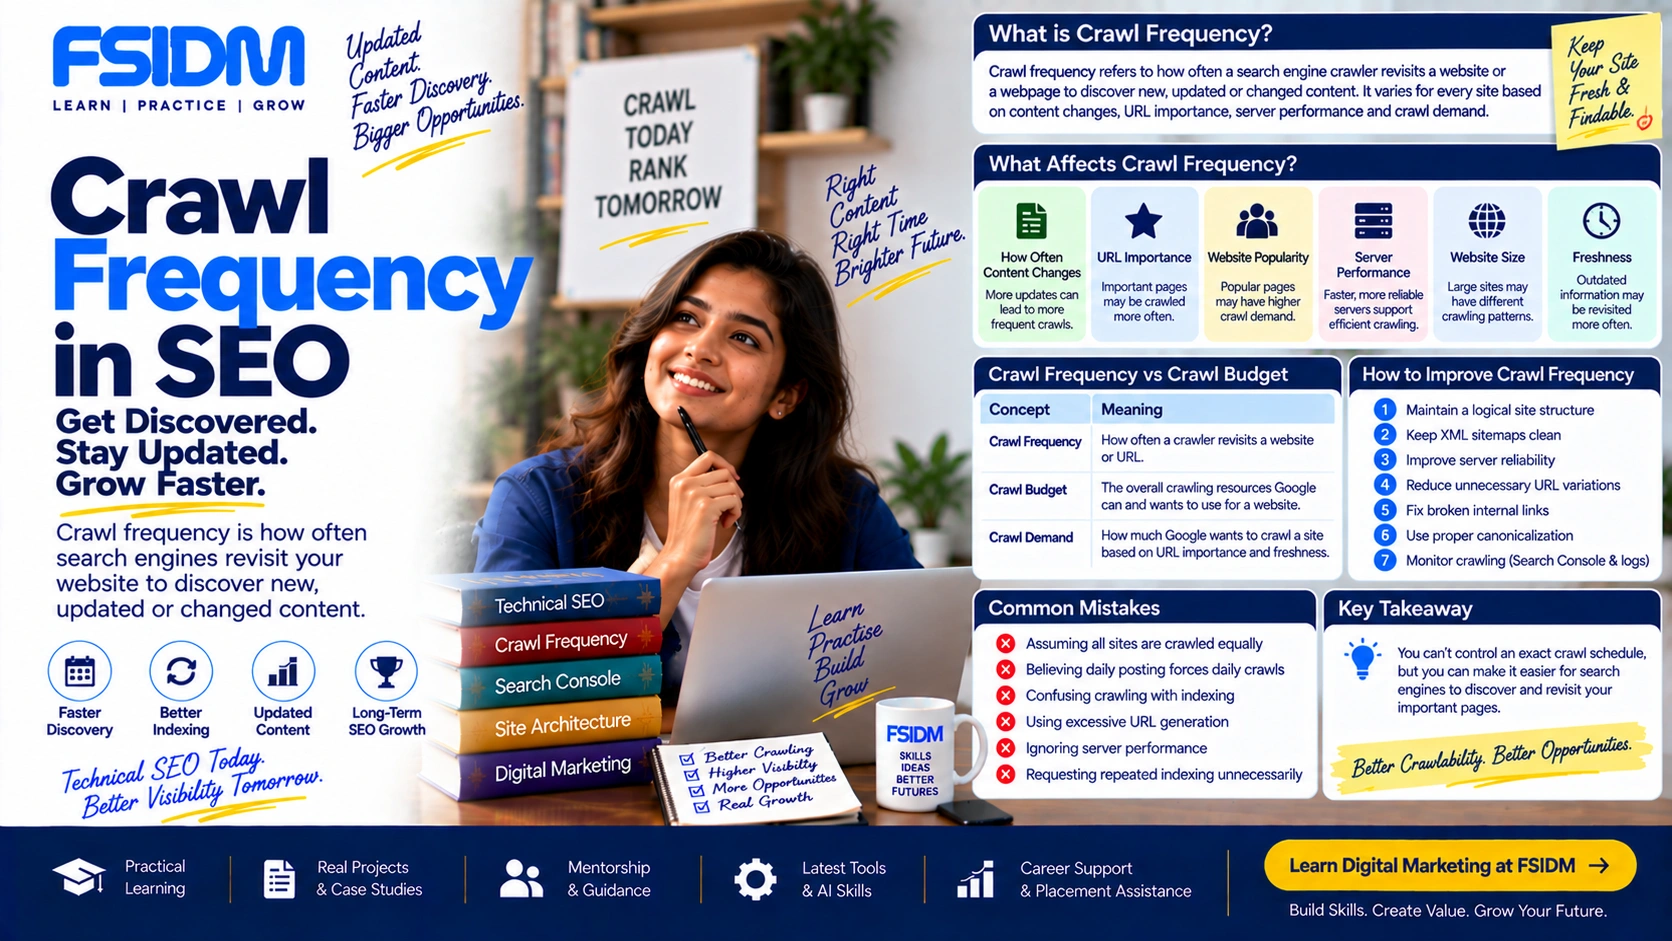
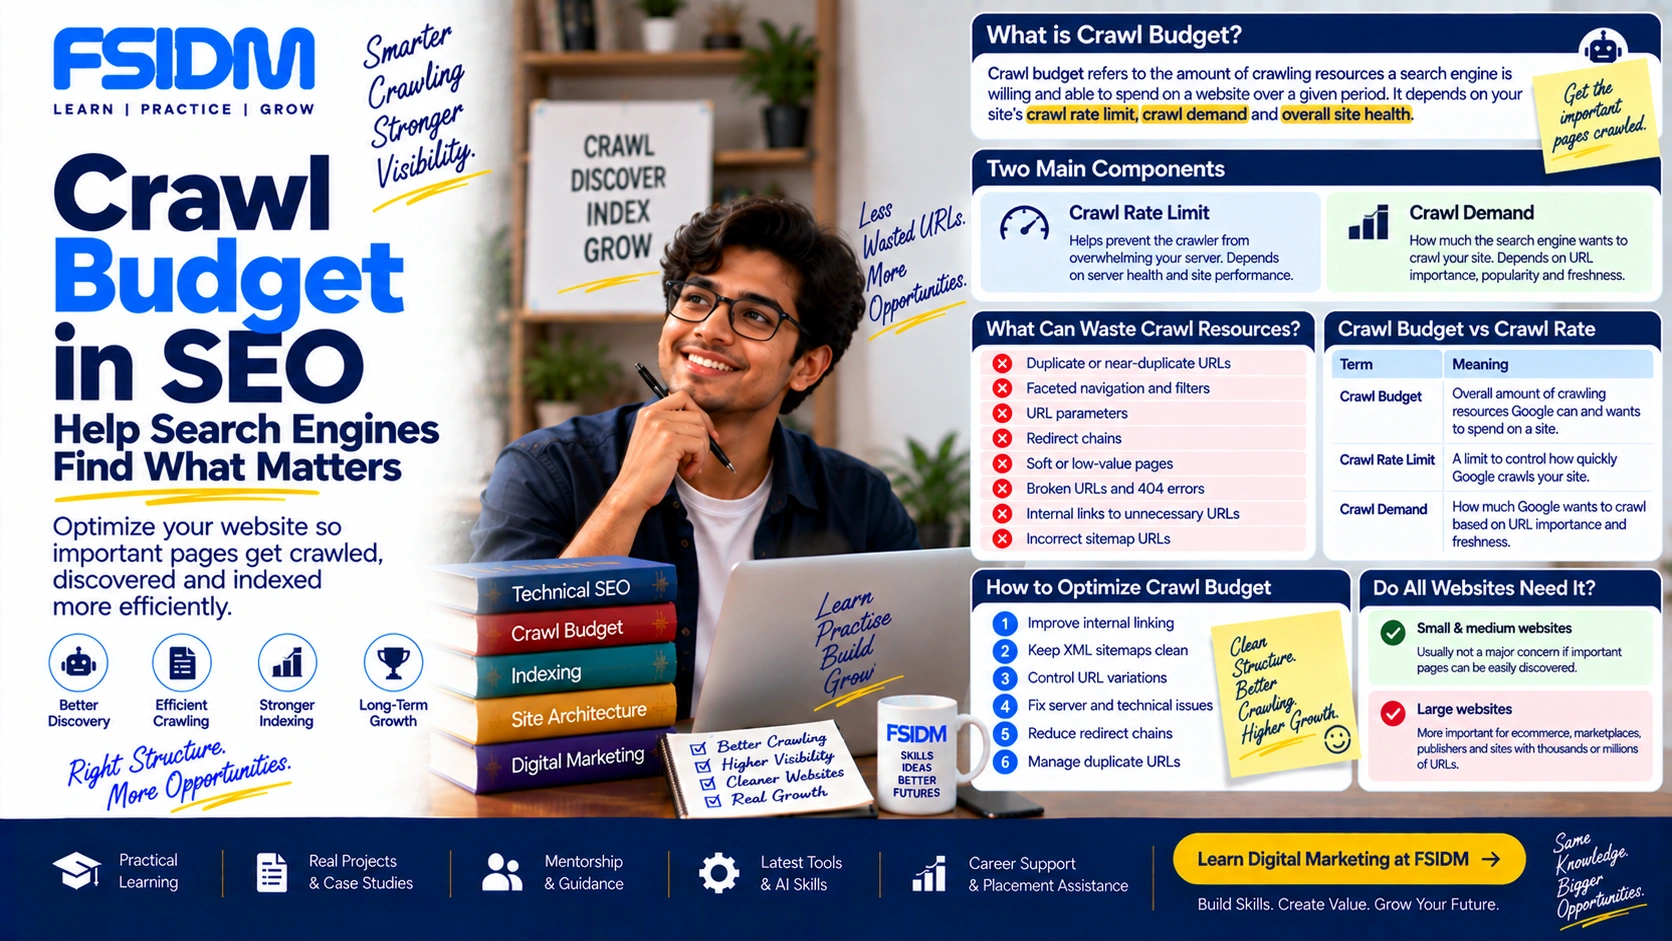
Index bloat and crawl-budget problems are related, but they are not the same thing.
| Concept | Meaning |
|---|---|
| Index Bloat | An unnecessarily large set of indexed URLs, often containing low-value, duplicate, or unwanted pages. |
| Crawl Budget | The crawling resources Google can and wants to use for a website. |
| Crawl Waste | Crawling resources being spent on URLs that are not useful or important. |
Index bloat can contribute to inefficient crawling in some situations, but the two problems should be diagnosed separately.
Why Can Index Bloat Be a Problem?
1. It Can Dilute Website Quality Signals
A website with a large number of low-value URLs may create a less focused search footprint. However, this should not be interpreted as an automatic Google penalty simply because many pages are indexed.
2. It Can Create Duplicate Search Results
When multiple URLs represent substantially the same content, search engines may have difficulty determining which version is most appropriate to show.
3. It Can Create Crawling Inefficiencies
On large websites, unnecessary URL variations can consume crawling resources that could otherwise be used to discover or revisit important pages.
4. It Can Make SEO Analysis More Difficult
A bloated index can make it harder for SEO teams to understand which pages are genuinely contributing to organic visibility and which URLs are simply being discovered or indexed without strategic value.
How to Identify Index Bloat
Finding index bloat requires more than checking the total number of indexed URLs. SEO professionals should compare indexed URLs with the website’s actual content architecture and search visibility.
- Review Google Search Console: Examine indexing reports and indexed URL patterns.
- Analyze indexed URL types: Look for parameters, filters, tags, archives, duplicate paths, and other patterns.
- Compare indexed pages with your sitemap: Investigate important differences between URLs you intentionally submit and URLs search engines discover elsewhere.
- Review organic traffic: Identify indexed pages that consistently provide little or no search value.
- Analyze server logs: Large websites can use logs to understand how crawlers interact with different URL patterns.
- Inspect search results carefully: Search operators can provide clues, but they should not be treated as an exact count of Google’s index.
How to Fix Index Bloat
1. Decide Which URLs Deserve to Be Indexed
Start by defining which pages provide genuine standalone value for search users. Do not remove pages simply because they receive little traffic; evaluate their purpose, uniqueness, business value, and search intent.
2. Improve URL Architecture
Reduce unnecessary URL variations created by filters, parameters, sorting systems, and other technical mechanisms.
3. Use Canonicalization Correctly
When multiple URLs contain substantially similar content, appropriate canonical signals can help search engines understand the preferred URL. Canonicalization is a hint, not an absolute guarantee.
4. Use Noindex Where Appropriate
For pages that should remain accessible to users but should generally not appear in search results, a noindex directive may be appropriate.
5. Remove Truly Unnecessary Pages
If a page has no useful purpose, consider whether it should be removed and whether the appropriate response should be a 404 or 410, depending on the situation.
6. Keep XML Sitemaps Clean
XML sitemaps should focus on important URLs that are eligible for indexing. Avoid treating sitemaps as a storage location for every URL on the website.
Robots.txt Is Not a Direct Fix for Index Bloat
A common mistake is to block unwanted URLs in robots.txt and assume that this removes them from Google’s index.
Robots.txt controls crawling access; it does not directly provide a noindex instruction. If Google cannot crawl a URL, it may still discover the URL through other signals and potentially retain information about it.
Therefore, the correct technical solution depends on whether your goal is to prevent crawling, prevent indexing, consolidate duplicate URLs, or remove content completely.
Index Bloat Example
Consider an online store with 20,000 genuine product and category URLs. Its filtering system also creates 300,000 combinations such as color, size, brand, price range, and sorting parameters.
If many of those combinations become indexed despite having little unique search value, the website may have an index-bloat problem. The SEO team could review the URL architecture, internal linking, canonicalization, indexing controls, and sitemap configuration to reduce unnecessary indexable URLs.
Index Bloat and JavaScript Websites
JavaScript-driven websites can also create unwanted URLs through dynamic routing, internal search, filters, or application states. SEO teams should test how these URLs are discovered, rendered, crawled, and indexed rather than assuming that a URL is invisible simply because it is generated through JavaScript.
Common Index Bloat Mistakes
- Assuming every large index is automatically bloated.
- Removing pages solely because they have low traffic.
- Using
robots.txtas a substitute fornoindex. - Adding every URL to an XML sitemap.
- Using canonical tags without understanding which URLs should actually be consolidated.
- Deleting URLs without considering redirects, backlinks, internal links, and user needs.
- Confusing crawling, indexing, and ranking as the same process.
FAQs About Index Bloat
What is index bloat in simple words?
Index bloat is when a website has many indexed URLs that are unnecessary, duplicate, low-value, outdated, or otherwise not useful for search users.
Does index bloat cause a Google penalty?
There is no general Google penalty simply for having a large number of indexed URLs. The concern is whether unnecessary or low-quality pages create technical, content, or search-quality problems for the website.
How do I check for index bloat?
Review Google Search Console, URL patterns, XML sitemaps, organic traffic, internal links, and—especially for large websites—server logs. Look for unnecessary indexed URL patterns rather than focusing only on the total indexed count.
Can noindex fix index bloat?
noindex can be appropriate for URLs that should remain accessible but should generally not appear in search results. It is one possible solution, not a universal fix.
Is index bloat the same as crawl budget?
No. Index bloat concerns the set of URLs that are indexed, while crawl budget concerns the crawling resources Google can and wants to use for a website.
Interview Question
What is index bloat, and how would you diagnose and fix it on a large website?
A strong answer should explain that index bloat involves unnecessary or low-value indexed URLs. Mention URL-pattern analysis, Google Search Console, XML sitemaps, server logs, canonicalization, noindex, URL architecture, and removal of genuinely unnecessary pages.
Interview Tip
Do not say “more indexed pages are bad.” A large website can legitimately have a large index. Explain that the problem is unnecessary indexed URLs, not index size by itself.
Learn Technical SEO Practically with FSIDM
Index management is an important part of technical SEO, particularly for ecommerce stores, marketplaces, publishers, and other large websites with complex URL structures.
At FSIDM, digital marketing and SEO are approached with a practical, industry-focused mindset, helping learners understand modern SEO concepts and how they are applied to real websites.