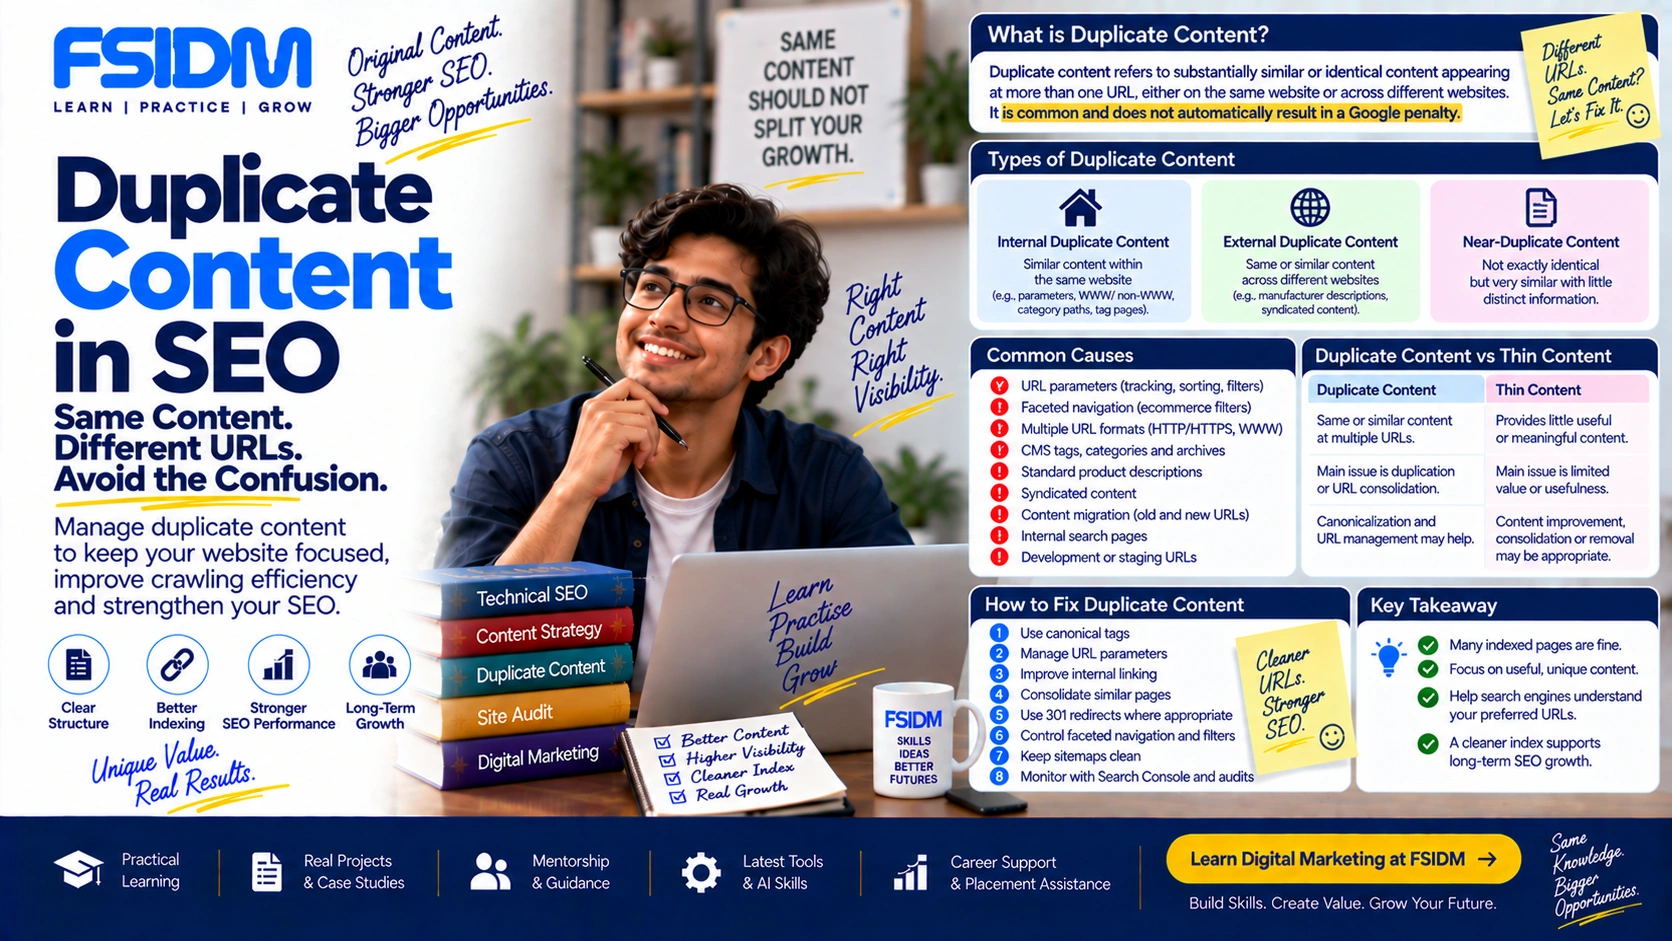
Duplicate content refers to substantially similar or identical content appearing at more than one URL, either on the same website or across different websites.
Duplicate content is common on the web and does not automatically result in a Google penalty. Search engines can often identify duplicate or near-duplicate versions and choose which URL to show in search results. The SEO challenge is making sure search engines understand which version is preferred and that important pages are not unnecessarily competing with multiple URL variations.
What Is Duplicate Content?
Duplicate content occurs when substantially the same information is available through multiple URLs. The duplication can be intentional or accidental.
For example, an ecommerce product might be accessible through multiple category paths, or a website might generate separate URLs for tracking parameters. Both URLs could display essentially the same page content even though their addresses are different.
Types of Duplicate Content
1. Internal Duplicate Content
Internal duplicate content occurs when similar or identical content appears across multiple URLs within the same website.
Common examples include:
- Multiple URLs leading to the same product page
- HTTP and HTTPS versions of a page
- WWW and non-WWW versions when not properly consolidated
- URL parameters used for tracking or sorting
- Print-friendly versions of pages
- Duplicate category, tag, or archive URLs
2. External Duplicate Content
External duplicate content occurs when the same or substantially similar content appears on different websites.
For example, a manufacturer may provide standard product descriptions that are reused by many online retailers. Multiple retailers can therefore end up publishing very similar descriptions.
3. Near-Duplicate Content
Near-duplicate content is not exactly identical but is sufficiently similar across pages that the pages provide little distinct information.
This can occur with location pages, product variations, filtered category pages, or automatically generated pages where only a few words change between URLs.
Common Causes of Duplicate Content
- URL parameters: Sorting, filtering, tracking, or session parameters can create multiple versions of a page.
- Faceted navigation: Ecommerce filters can generate many URL combinations containing similar content.
- Multiple URL formats: Technical configuration can make the same content accessible through different URL versions.
- CMS archives: Tags, categories, and date archives can repeat excerpts or full content.
- Product descriptions: Standard manufacturer descriptions may be reused across multiple websites.
- Syndicated content: Content may legitimately appear on multiple websites through distribution or syndication.
- Content migration: Old and new URLs may coexist after a website redesign or migration.
Does Duplicate Content Cause a Google Penalty?
Not automatically. Having duplicate content does not mean that Google will simply penalize a website.
Search engines generally try to identify duplicate or substantially similar versions and select a representative URL for search results. Problems can arise when duplication creates confusion about which URL should be indexed, splits signals between URLs, or causes search engines to spend resources crawling unnecessary URL variations.
There are separate situations involving deceptive or manipulative duplication where Google’s spam policies may become relevant, but ordinary duplicate content should not automatically be described as a penalty.
Duplicate Content vs Thin Content
| Duplicate Content | Thin Content |
|---|---|
| Substantially similar content exists at multiple URLs. | A page provides little useful or meaningful content. |
| The main issue is duplication or URL consolidation. | The main issue is limited value or usefulness. |
| Canonicalization and URL management may help. | Content improvement, consolidation, or removal may be appropriate. |
How Duplicate Content Can Affect SEO
1. Canonicalization Challenges
When multiple URLs contain similar content, search engines need to determine which URL should be treated as the primary version. Clear canonical signals can help communicate your preferred URL.
2. Indexing Complexity
Not every duplicate URL needs to appear independently in search results. Managing duplicate URLs can help keep the website’s searchable content more focused.
3. Crawling Inefficiency
On large websites, thousands of duplicate URL variations can consume crawling resources. This can be particularly important for ecommerce sites and other large platforms.
4. Split Signals
When substantially similar URLs are treated as separate pages, links and other signals may not be consolidated as effectively as they could be when the preferred URL structure is clear.
How to Find Duplicate Content
- Review Google Search Console: Examine indexing reports for URL patterns and canonical-related issues.
- Run a site crawl: SEO crawling tools can identify duplicate titles, duplicate content patterns, canonical tags, and multiple URL versions.
- Check URL parameters: Look for tracking, sorting, filtering, and other parameters that create duplicate versions.
- Review canonical URLs: Check whether important pages identify the preferred canonical version appropriately.
- Compare page templates: Identify pages where only small details change while the majority of the content remains identical.
How to Fix Duplicate Content
1. Use 301 Redirects
When duplicate URLs should no longer exist, a 301 redirect can consolidate visitors and signals toward the preferred URL when appropriate.
2. Use Canonical Tags
A rel="canonical" link element can indicate which URL should be considered the preferred version among substantially similar pages. Canonicalization is a signal to search engines, not an absolute command.
3. Improve Internal Linking
Link consistently to the preferred URL throughout the website. This reduces ambiguity and helps search engines understand your URL hierarchy.
4. Keep XML Sitemaps Clean
Include preferred, indexable URLs in XML sitemaps rather than unnecessary duplicate versions.
5. Consolidate Similar Pages
If multiple pages serve essentially the same search intent and provide limited unique value, consider combining them into a stronger, more comprehensive resource.
6. Create Unique Product and Location Content
Where appropriate, add genuinely useful information that makes each page valuable for its specific audience rather than changing only a location name or a few keywords.
Canonical Tag vs 301 Redirect
| Method | Best Used When |
|---|---|
| Canonical Tag | Multiple similar URLs need to remain accessible, but one version is preferred for search. |
| 301 Redirect | An old or duplicate URL should permanently send users to another URL. |
The correct solution depends on the reason the duplicate URLs exist and whether users need to access the alternate versions.
Duplicate Content Example
Imagine an ecommerce website where a product can be reached through these URLs:
example.com/shoes/running-shoes/product-a
example.com/shoes/sports/product-a
example.com/product-a?category=running
If all three URLs display essentially the same product page, the website should provide clear signals about the preferred URL instead of allowing unnecessary URL variations to become the main versions discovered through internal links and sitemaps.
Duplicate Content and AI-Generated Content
AI-generated content is not automatically duplicate content. The important question is whether the resulting content is substantially similar to existing content and whether it provides genuine value.
Using AI to produce pages that simply reproduce existing information at scale can create quality and duplication problems. SEO teams should prioritize original, useful, accurate content rather than generating large volumes of near-identical pages.
Common Duplicate Content Mistakes
- Assuming every duplicate page results in a Google penalty.
- Using canonical tags without checking whether the selected canonical URL is appropriate.
- Blocking duplicate URLs with robots.txt and assuming they are automatically removed from the index.
- Creating hundreds of near-identical location pages with minimal unique value.
- Allowing multiple URL versions to be used inconsistently in internal links.
- Including duplicate or non-canonical URLs in XML sitemaps.
- Deleting duplicate pages without considering redirects and user access.
FAQs About Duplicate Content
What is duplicate content in simple words?
Duplicate content is substantially similar or identical content available at multiple URLs, either within one website or across different websites.
Does duplicate content hurt SEO?
Duplicate content does not automatically result in a penalty. However, extensive duplication can create indexing, canonicalization, crawling, and URL-management challenges.
How much duplicate content is allowed?
There is no universal percentage that determines whether content is “allowed.” Search engines evaluate pages and choose how to handle substantially similar content based on context and other signals.
Should I delete duplicate content?
Not always. Depending on the situation, you may use canonicalization, redirects, consolidation, noindex, or simply leave legitimate duplicate content accessible. The correct solution depends on why the duplicate exists.
Is syndicated content duplicate content?
Syndicated content can create duplication because similar material appears on multiple websites. Publishers should use appropriate distribution and canonicalization practices where relevant and follow search-engine guidance.
Interview Question
What is duplicate content, and how would you handle it on an ecommerce website?
A strong answer should explain internal, external, and near-duplicate content, then discuss URL parameters, canonical tags, redirects, internal linking, clean sitemaps, and consolidation of genuinely overlapping pages.
Interview Tip
Avoid saying “duplicate content is always penalized.” A better answer is that duplicate content is common on the web and becomes an SEO concern when search engines need to choose between substantially similar URLs or when duplication creates unnecessary crawling and indexing complexity.
Learn Technical SEO Practically with FSIDM
Understanding duplicate content is an essential technical SEO skill, especially when working with ecommerce stores, large websites, migrations, CMS platforms, and complex URL structures.
At FSIDM, digital marketing and SEO are approached with a practical, industry-focused mindset, helping learners understand modern SEO concepts and how they are applied to real websites.